NVIDIA Nemotron Labs Dory1.0-4B
A downloadable English reasoning model with adjustable inference loops, long context, and local tool-calling APIs.
Analyze multimodal inputs and generate text for complex coding, scientific reasoning, and tool-connected agent applications.
Visit website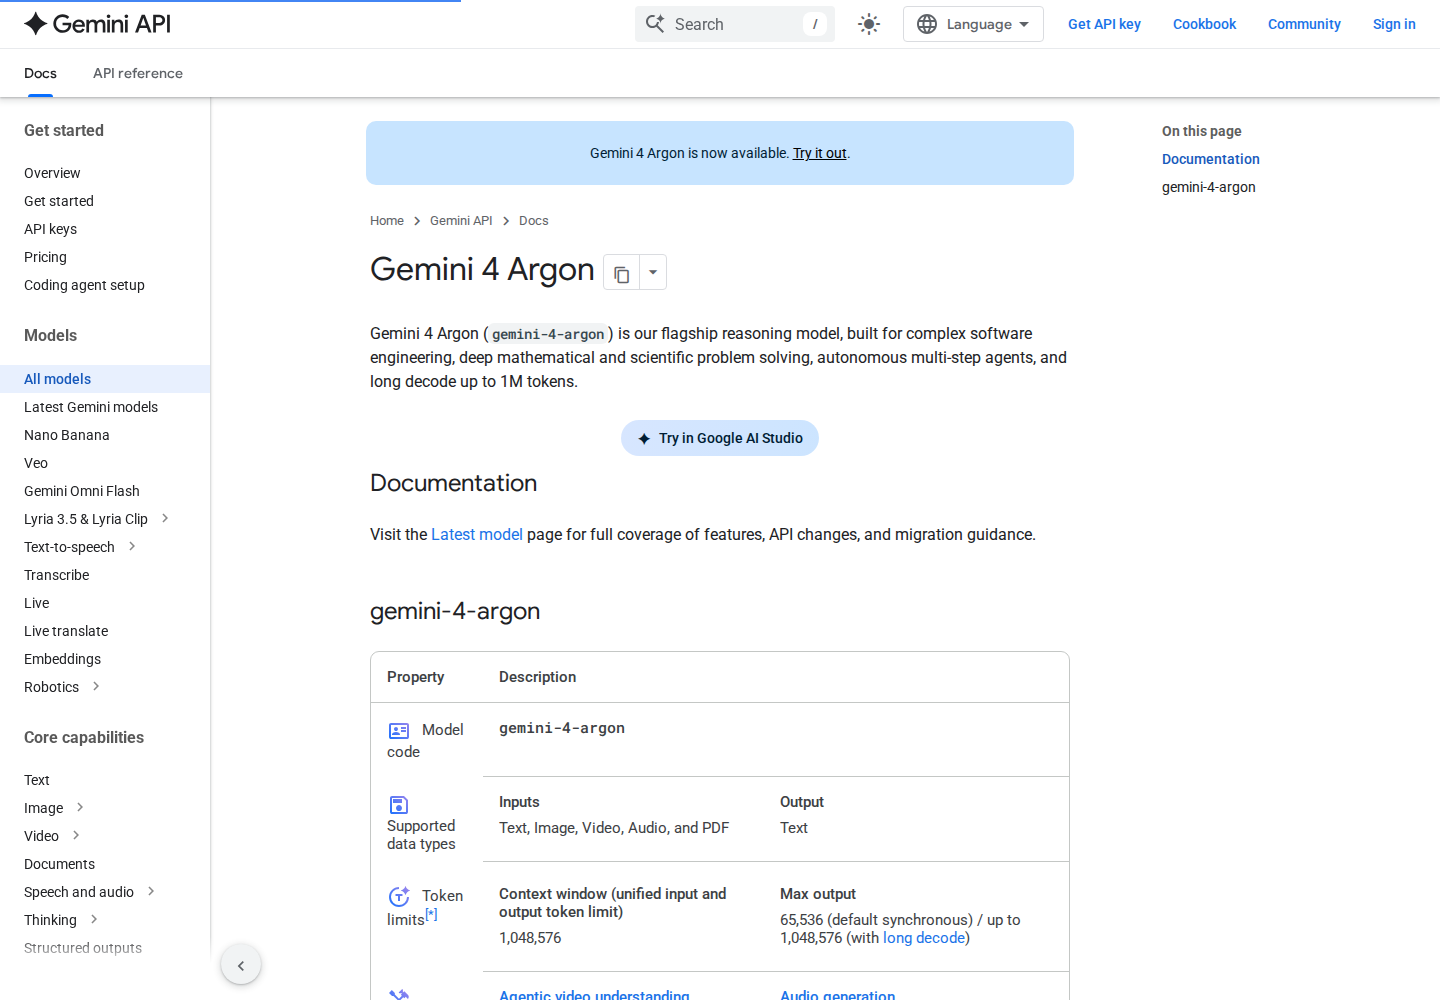
Gemini 4 Argon is Google’s stable reasoning model for complex coding, mathematical and scientific problems, and multi-step agents. It accepts text, images, video, audio, and PDFs and generates text.
Available through the Gemini API and Google AI Studio, Argon offers adjustable thinking effort and long responses through background execution or GenerateContent client-side continuation.
Combine written instructions with images, video, audio, and PDF documents.
Choose low, medium, or high thinking. Medium is the default; higher effort increases token use and first-token latency.
Input, thinking, and output share 1,048,576 tokens. The default synchronous output limit is 65,536 tokens.
Responses beyond 65,536 tokens can use background execution with a higher output limit or GenerateContent client-side continuation. Background execution manages continuation server-side. Both remain subject to the shared context and thinking budget.
Supports function calling, structured outputs, code execution, file search, search grounding, Google Maps grounding, and URL context.
Batch API, Flex inference, and Priority inference offer additional consumption options with separate prices.
Analyze implementation material and develop proposed fixes for difficult coding tasks.
Combine documents and visual inputs to develop mathematical or scientific explanations for review.
Connect reasoning to application functions and configured information tools.
Argon is unavailable on the Free tier. API billing is token-based, including thinking tokens in output charges. Standard introductory rates apply through November 30, 2026, with higher rates from December 1. Grounding, Batch, Flex, and Priority have separate pricing.
Output charges include thinking tokens. Implicitly cached input costs USD 0.10 per million tokens. Rates apply to Standard Paid Tier usage.
Output charges include thinking tokens. Implicitly cached input costs USD 0.20 per million tokens. Rates apply to Standard Paid Tier usage.
No. It accepts image and audio inputs but generates text.
No. GenerateContent also supports client-side continuation. Both options share the context window and thinking budget.
No. Gemini 4 Argon is unavailable on the Free tier and requires paid access.